Qualcomm CEO Says Smartphones Will Run 100B AI Models by 2028
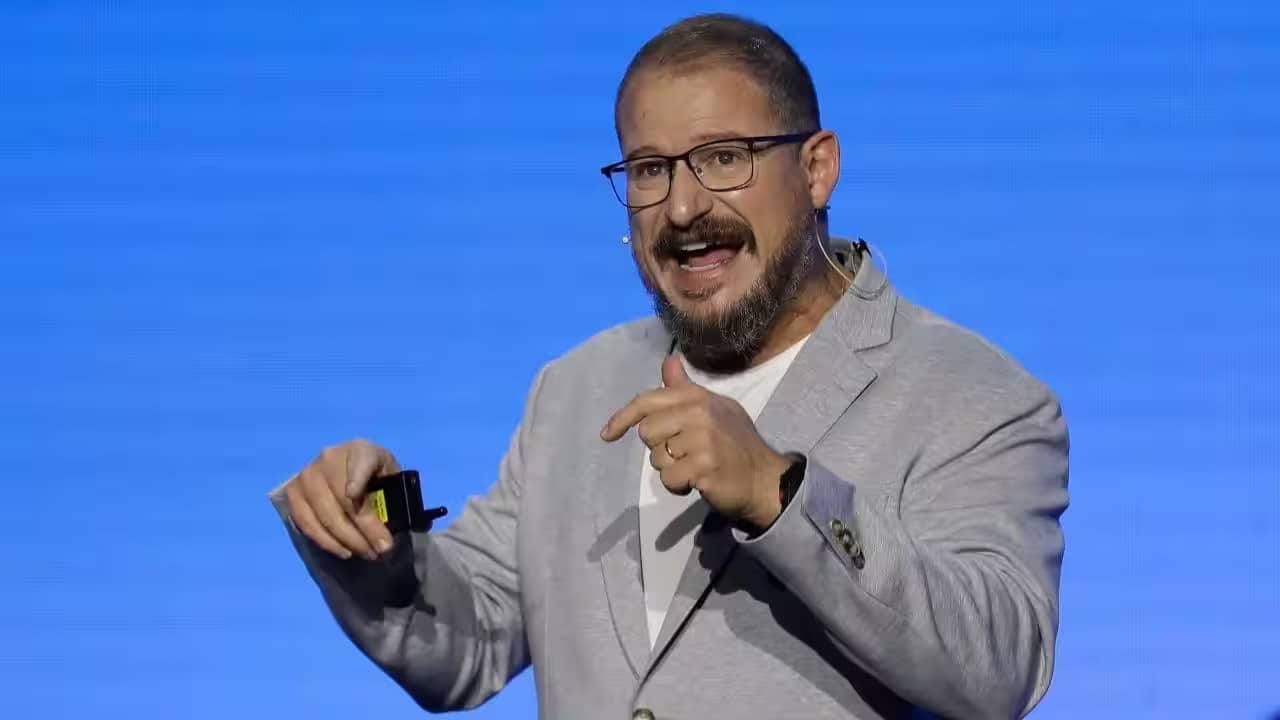
Qualcomm CEO Cristiano Amon believes smartphones will be able to continuously run AI models with 100 billion parameters by 2028, despite major challenges involving memory capacity, cost, and heat.
Qualcomm CEO Cristiano Amon believes smartphones will be able to continuously run AI models with 100 billion parameters by 2028, despite major challenges involving memory capacity, cost, and heat.
Article outline
- What happened
- Background
- Why it matters
- The key numbers
- The details
- The bottom line
Key points
- Apple and Qualcomm have began addressing some hardware limitations through changes in chipset packaging with platforms such as the A20 Pro and Snapdragon 8 Elite Extreme Gen 6.
- Qualcomm CEO reveals AI firms want phones running 100-billion-parameter models continuously by 2028-and confirms some are building phones.
- Speaking with Fireside Alpha, Amon remarked AI businesses are already developing smartphones capable of running 100B sizeable language models.
- A 100-billion-parameter model quantized to 4-bit would require regarding 50GB of memory just to store its parameters.
- Another option would be to employ a smaller distilled model with around 20 billion to 30 billion parameters.
Speaking with Fireside Alpha, Amon remarked AI businesses are already developing smartphones capable of running 100B sizeable language models. He did not name the firms involved.
Memory remains one of the biggest obstacles to running such sizeable AI models on smartphones. With the current DRAM supply situation, smartphones are unlikely to move beyond the 16GB RAM range in the near future. Amon, nevertheless, expects manufacturers to equip future devices with significantly more memory, even as DRAM remains expensive and supply stays tight. Running 100B AI Models Would Require Much More RAM. Current hardware makes running a conventional 100B model locally extremely tough.
In practice, a 100-billion-parameter model quantized to 4-bit would require regarding 50GB of memory just to store its parameters. Smartphones would additionally need further memory for the operating system, applications, and the model's context cache.
Even reducing the model to 2-bit quantization would require around 25GB of memory for the model alone. That figure remains higher than the memory capacity of most current smartphones. Google Launches Granola-Like Offline AI Notes and Transcription App.
Cristiano Amon: I have to be careful not to disclose names, but some AI companies-some of the firms at the forefront of AI-are. Pic.twitter.com/3Gded1a9Ld. Fireside Alpha (@firesidealpha) October 10, 2026.
For context, the difficulty comes as smartphone manufacturers have already kicked off moving away from higher RAM configurations since of rising DRAM costs and supply constraints. Just a year ago, some Android smartphones offered as much as 24GB of LPDDR5X RAM.
Memory capacity is additionally not the only challenge. Continuously running such a sizeable model would generate substantial heat. Sustained AI workloads could cause smartphones to reach their thermal limits and throttle performance. Quantization and New Chip Packaging Could Support.
Nevertheless, these changes do not remove the underlying memory bottleneck. More aggressive approaches would still be necessary to run 100B models on smartphones.
One option is aggressive model quantization. A 1-bit version could significantly reduce memory requirements and potentially allow a sizeable model to fit within smartphone RAM.
For context, the downside is model quality. Performance can degrade significantly when quantization goes below 4-bit, particularly for reasoning workloads. OpenAI Is Turning ChatGPT Into a More Interactive Interface. Sparse MoE Models Could Offer Another Solution.
Another feasible approach is using sparse Mixture-of-Experts, or MoE, models with expert offloading.
MoE models activate only a small portion of their experts for each token. Active experts could remain in RAM while the rest of the model stays on the smartphone's flash storage.
This could reduce the amount of DRAM required at any given time.
Apple has previously researched running sizeable language models using flash storage. Nevertheless, smartphone UFS and NVMe storage remain slower than DRAM. It can reduce inference speeds when model data has to move between storage and memory. Smaller Distilled Models May Be More Practical.
Such a model could potentially approach the quality of a 100B model while requiring significantly fewer hardware resources. This could be a more practical strategy for smartphone manufacturers.
For now, Amon has not provided a detailed roadmap explaining how smartphones will overcome the memory, storage, power, and thermal limitations required to continuously run 100B models by 2028.
Still, technologies such as sparse MoE architectures, flash-based model storage, aggressive quantization, and smaller distilled models could provide feasible paths toward running increasingly capable AI models directly on smartphones. Stay Connected with ProPakistani.
Obtain the latest tech news, telecom insights, and product launches wherever you prefer. Follow on Google Discover. Follow on Google News Join WhatsApp. See more ProPakistani stories in Google Search and Top Stories.
Technology and Automotive Specialist covering the latest cars, smartphones, AI breakthroughs, and.
Taken together, the developments around qualcomm CEO Says Smartphones Will Run 100B AI Models by 2028 point to a situation that is still moving, and the coming days should bring more clarity.